Vibe Coding vs Traditional Coding: When Each Wins
Verdict: Vibe-Code Some Things, Hand-Code Others
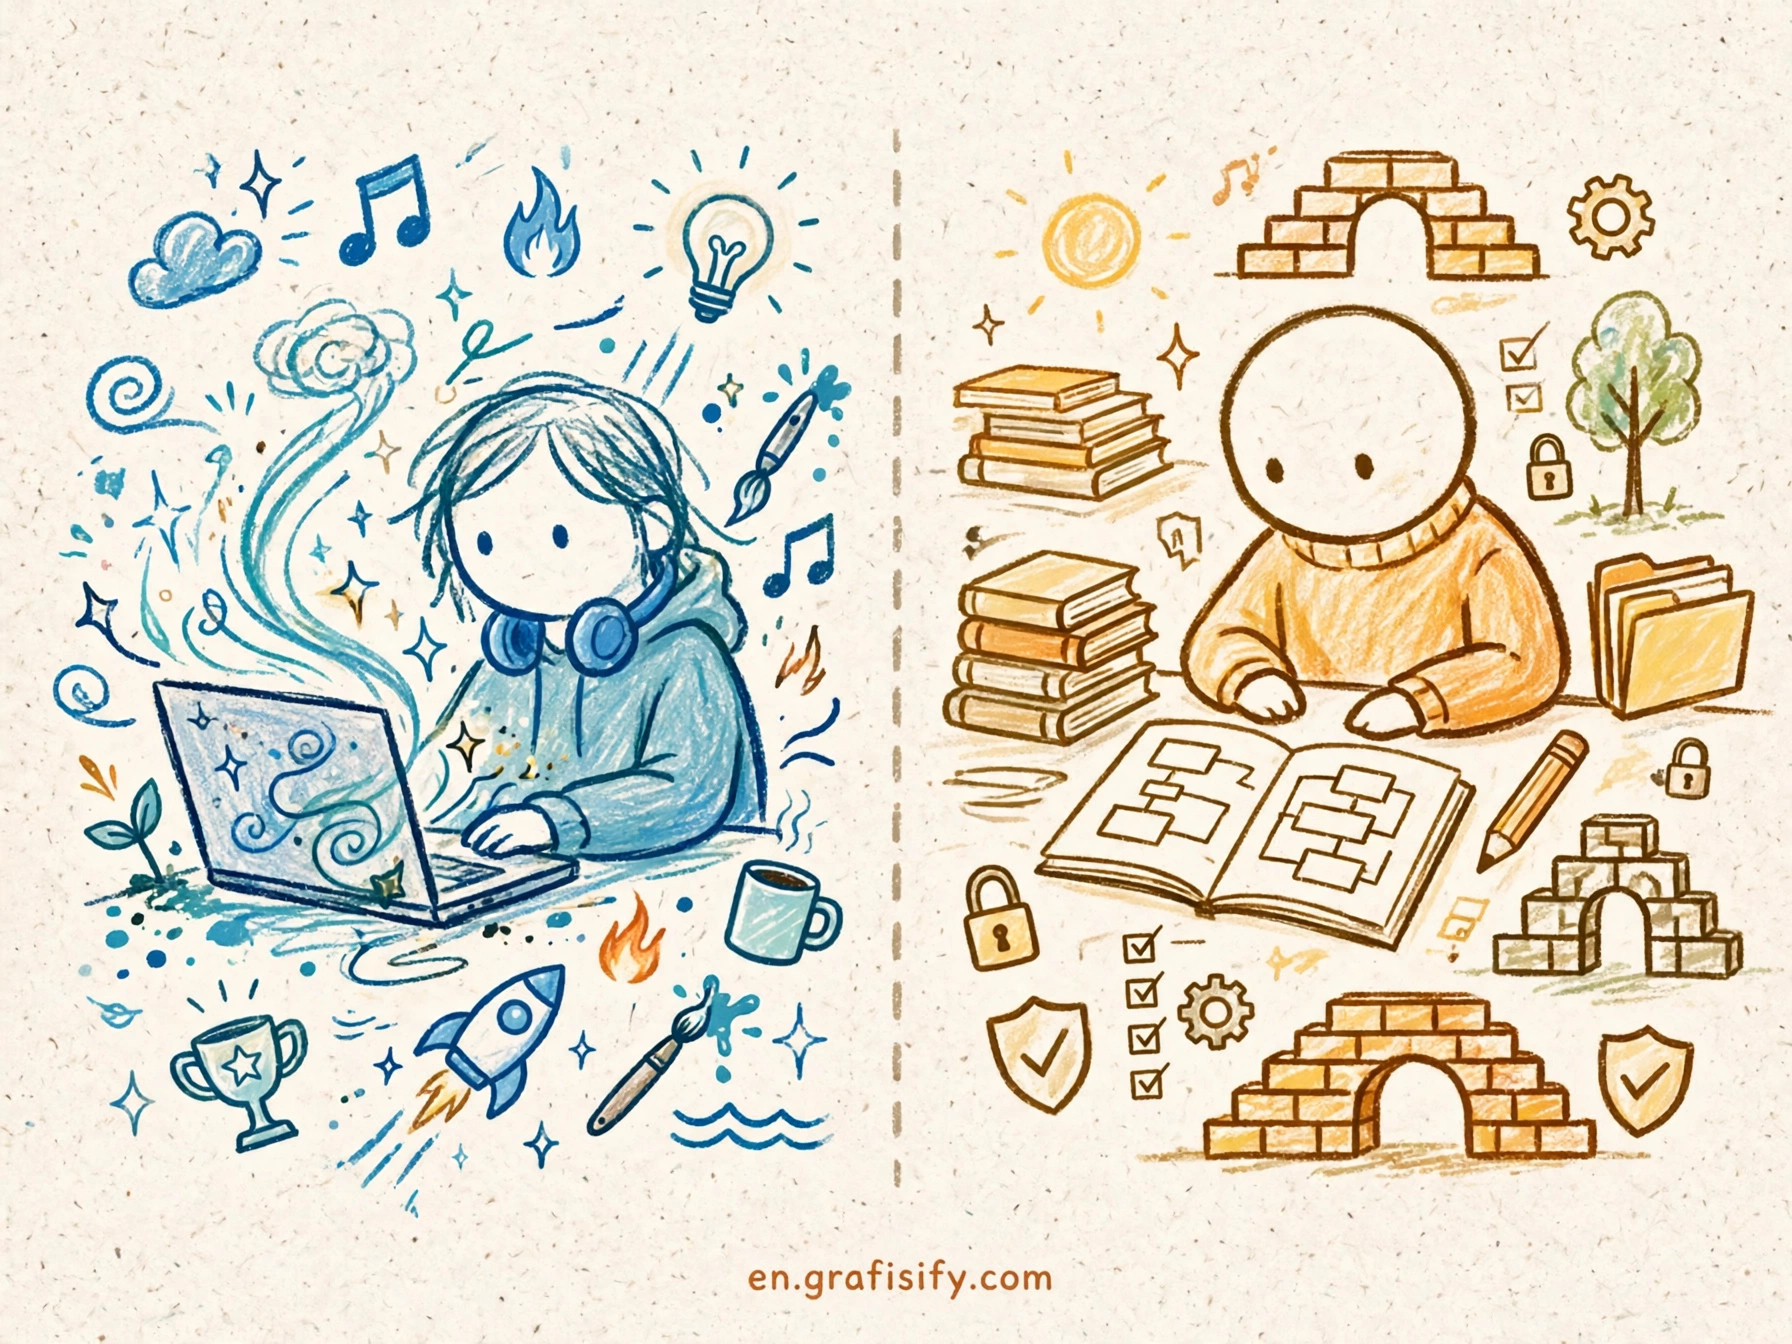
Vibe coding wins speed contests on low-stakes work. Traditional coding wins trust contests on high-stakes work. The split between the two matters more than the tools on either side.
- Vibe-code prototypes, throwaway scripts, and commodity CRUD you can verify in minutes.
- Hand-code auth, payments, migrations, compliance, and performance-critical paths.
- Use a hybrid for the rest: AI drafts the first version, a human owns the result and the review.
The numbers below back this split. Adoption is near-universal, trust stays low, and measured speed gains are uneven. I read the survey data and the controlled trials before writing this, and the gap between hype and evidence is the whole story.
Vibe Coding and Traditional Coding, Defined
Vibe coding means describing intent in plain language and letting an AI model write the code. You prompt, the model generates, you run the result, and you iterate by describing what to change. The loop feels conversational. The code itself becomes a byproduct of the conversation rather than the main artifact you shape by hand.
Traditional coding means writing code line by line, choosing each abstraction, and owning each decision in the file. You read the code you ship. You can explain why each function exists. The work is slower at the keyboard and faster at review time, because nothing in the file surprises its author.
Also Read:
Most real work sits between these poles. A developer prompts an agent for a first draft, reads the diff, rewrites the parts that smell wrong, and keeps the parts that hold up. That hybrid is where the strongest teams live. For the full definition and the origin of the term, see what vibe coding means.
Three criteria decide which side of the split a task belongs on: blast radius, verifiability, and novelty. Blast radius asks what breaks if the output is wrong. Verifiability asks whether you can check the result in minutes. Novelty asks whether the problem has a known pattern or demands fresh design. A task with a small blast radius, fast verification, and a familiar pattern is a vibe-coding task. A task with a large blast radius, slow verification, or genuine novelty belongs in human hands.
The Data: Adoption Is Up, Measured Speed Is Not
Developers adopted AI coding tools at a pace few technologies match. The Stack Overflow Developer Survey 2025 found that 84% of respondents are using or planning to use AI tools in their development process, up from 76% the year before. The 2026 survey pushed the figure further into daily habit: 73% of respondents now use coding assistants and agents daily, and 31% of daily users spend upwards of four hours per day with them. AI coding moved from experiment to default workflow in about two years.

Trust did not keep pace with adoption. The 2025 survey found that 46% of developers actively distrust the accuracy of AI tools, against 33% who trust it, and a mere 3% report high trust in the output. The 2026 survey adds a condition that explains the gap: 48% of developers trust AI when they can validate the answers with ease, while 16% extend that trust to most tasks that are not important work decisions. Trust tracks verifiability. Developers trust the tool where they can check it, and they withhold trust where they cannot.
Frustration follows the same pattern. The 2025 survey names the top complaint plainly: 66% of developers cite AI solutions that are almost right, but not quite. Another 45% say debugging AI-generated code costs more time than writing it by hand. Near-miss output is the tax on vibe coding. The code compiles, the demo runs, and the bug hides one layer down, in a place the prompt left out.
Controlled evidence sharpens the picture. A METR randomized controlled trial from 2025 put experienced open-source developers on their own repositories, half with AI tools and half without. The developers using AI took 19% longer than those working without it. METR frames the result as a snapshot of early-2025 AI capabilities in one relevant setting, and the tools improved since then, yet the finding still cuts against the speed story. Experience plus AI did not equal speed. Review load, context switching, and debugging near-miss output ate the gains.
GitHub data shows the other side of the same coin. As of September 2026, developers start more than 40% of pull requests with an agent, up from 17% in March. Among GitHub Copilot monthly active users, 55% now use agentic features, up from 35% a year ago. Agent-drafted code dominates the intake, and it merges fine, because human review still gates the merge. Adoption and review grew together.
DORA gives the framing that ties these threads together. The State of AI-assisted Software Development report describes AI as an amplifier, magnifying an organization’s existing strengths and weaknesses. The greatest returns on AI investment come from a strategic focus on the underlying organizational system, not from the tools alone. Strong teams get stronger with agents. Weak review habits get exposed faster.
For the source data behind this section, see the Stack Overflow Developer Survey 2025 on AI, the 2026 survey on AI usage, the METR trial on AI and experienced developers, the GitHub Octoverse 2026 report on agents, and the DORA report on AI-assisted software development.
Comparison Table: Which Approach Wins Where
The table below applies the three criteria from the definitions section to common tasks. Read the why column first. It carries the decision logic, and the winner follows from it.
| Task type | Vibe coding | Traditional coding | Why |
|---|---|---|---|
| Greenfield demo or prototype | Wins | Slower start | Blast radius is tiny and verification takes minutes. |
| Internal script or one-off tool | Wins | Overkill | You run it, you see the output, you throw it away. |
| Commodity CRUD feature | Wins | Slower | The pattern exists in a thousand codebases already. |
| Auth and payments | Loses | Wins | A near-miss here leaks credentials or loses money. |
| Database migrations | Loses | Wins | A bad migration is hard to reverse in production. |
| Performance-critical hot paths | Loses | Wins | Speed needs measurement and profiling, not guesses. |
| Regulated or compliance code | Loses | Wins | Auditors want a human who can explain each line. |
| Debugging a production incident | Loses | Wins | You need a mental model of the system, not a new draft. |
The pattern is consistent. Vibe coding wins where the cost of being wrong is low and the check is fast. Traditional coding wins where the cost of being wrong is high and the check is slow. The table also explains the hybrid default: most features mix both kinds of work, so most features deserve both approaches in different parts.
The Hidden Cost Nobody Prices In: Debugging, Review, and Tech Debt
Speed claims for vibe coding count generation time and skip the rest of the ledger. The 66% near-miss figure and the 45% debugging figure from the Stack Overflow survey describe the other side of that ledger. Generation takes seconds. Verification takes the afternoon. A developer who prompts a feature into existence still has to read it, test it, and fix the parts the model guessed wrong. I have watched teams celebrate a ten-minute feature and spend two days untangling its edge cases.
Review load grows with agent output. GitHub data shows agents now draft the first version of more than 40% of pull requests. Each of those drafts needs a human reviewer who understands the code well enough to catch a subtle error. Reviewers carry that load on top of their own work. Teams that vibe-code heavily without expanding review capacity create a bottleneck at the merge queue, and the bottleneck shows up as slower shipping, not faster.
Near-miss defects compound into tech debt. A model writes plausible code that passes the happy path and fails on the second input shape, the empty list, or the expired token. Those failures surface weeks later, far from the prompt that caused them. The fix costs more than the original generation saved, because the developer who fixes it has to reconstruct intent the original author skipped. See finding and fixing vibe-coded tech debt for the cleanup pattern, and how to build LLM evals that catch real failures for a testing approach that fits agent-written code.
Security holes follow the same shape. Generated code tends to follow the most common pattern in training data, and the most common pattern is often the least secure one: string-built queries, permissive CORS settings, secrets in logs, missing rate limits. A human reviewer catches these when the reviewer knows what to look for. A team that ships agent output without a security pass ships the training data average, flaws included. Read shipping vibe-coded apps without security holes before your next agent-written deploy.
The honest accounting looks like this: vibe coding shifts cost from writing to verifying. Teams that invest in verification keep the speed. Teams that skip verification pay the cost later, with interest, in debugging sessions and incident reviews. The tool did not create this tradeoff. It made the tradeoff visible.
A Five-Question Workflow Before You Start
Use these five questions before you prompt anything. I use them myself, and they take two minutes and save the two-day debugging sessions described above.
- Verification: you can check the result in minutes, by running it and reading the output.
- Blast radius: a wrong answer costs minutes of your time, not customer data or revenue.
- Precedent: the pattern already exists in your codebase, a library, or a well-known recipe.
- Constraints: no compliance rule or performance budget forbids shortcuts in this code.
- Ownership: you will still maintain this code in six months, or someone on your team will.
Five yes answers mean vibe-code it, then review the diff line by line. Three or more no answers mean hand-code it, and use the agent for narrow subtasks inside the work, like boilerplate or test scaffolding. Mixed answers mean split the task: vibe-code the low-stakes parts, hand-code the parts where a no answer appeared.
Scope discipline matters as much as the answers. Agents degrade as context grows, so keep each prompt small and each file short. The MCP guide on how AI coding tools get context explains why long context breaks agent accuracy. A tight scope is the cheapest quality control available. For a full solo-developer routine built around this split, see the vibe coding workflow guide for solo developers.
Conclusion: Run Your Own One-Week Experiment
The verdict holds: vibe-code the throwaways, the prototypes, and the commodity features you can verify in minutes. Hand-code auth, payments, migrations, compliance, and hot paths. Run a hybrid everywhere else, with AI drafting and a human owning the result. The data supports this split. Adoption is near-universal, trust stays conditional on verification, and the controlled trial shows speed gains are far from guaranteed.
Run your own test instead of taking my word for it. Split one week in half. Vibe-code the low-stakes half and hand-code the high-stakes half. Track two numbers: cycle time from idea to merged code, and bug count in the two weeks after merge. Compare the halves with your own data, then keep the approach that wins on your codebase, with your team, under your review habits. Share the results in the comments. Your numbers will teach the next reader more than any survey can.

Irfan is a Creative Tech Strategist and the founder of Grafisify. He spends his days testing the latest AI design tools and breaking down complex tech into actionable guides for creators. When he’s not writing, he’s experimenting with generative art or optimizing digital workflows.





 Artificial Intelligent
 Design & Creative
 Freelance
 Gadgets & Gear
 Insights
 Laptop
 Reviews
 Smartphone
 Tech Guides
 Vibe Coding






